




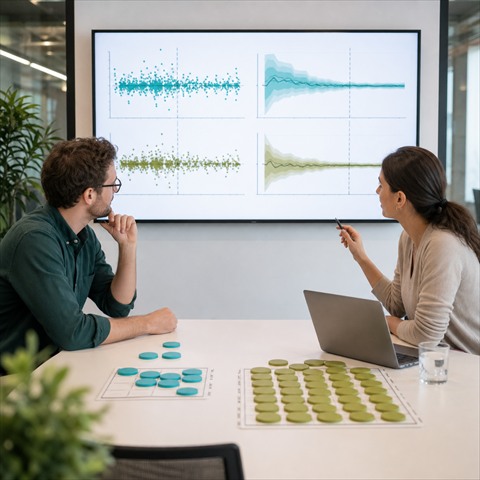
This is one of the most frequently asked questions by teams new to A/B testing: how many visitors, or how many conversions, do you need before you can trust the results of a test? The answer isn't a one-size-fits-all figure—it depends on your initial conversion rate, the magnitude of the change you're trying to detect, and the level of certainty you require before drawing a conclusion. This article explains these factors one by one, without complex mathematical formulas, so you can estimate the sample size needed for a reliable test yourself.
Why sample size is the most important question in a test
An A/B test compares the behavior of two groups of visitors exposed to two different versions of a page. But human behavior naturally varies from one visitor to another, regardless of the version viewed: some days, some times, some profiles convert better than others for reasons unrelated to the test being conducted. With a small sample size, this natural variation—statistical "noise"—can easily produce a difference between the two groups that resembles a real effect, when it is merely a random fluctuation.
Sample size is the primary factor in distinguishing a true signal from noise. The larger the sample, the more random fluctuations tend to cancel each other out, and the more likely a measured difference between two groups is to reflect a real effect of the change being tested rather than a coincidence. Running a test without having estimated the necessary sample size is tantamount to deciding in advance whether the result obtained will be reliable.
The starting conversion rate
The first factor to know is the current conversion rate of the page or user journey being tested, based on the metric that will be used to evaluate the test. This figure can be easily obtained from the data already available in your analytics tool: number of conversions divided by number of visitors, over a recent and representative period (excluding, if possible, periods with exceptional promotions or atypical traffic spikes).
This starting rate directly influences the required sample size: for the same effect, a low conversion rate (e.g., 1%) requires a larger sample than a high conversion rate (e.g., 20%) to detect the same relative difference. This is one reason why tests on infrequent metrics (a purchase, a subscription) generally require more traffic and time than tests on more frequent metrics (a click, a page scroll).
The MDE, or the magnitude of the effect that we are trying to detect
The MDE (Minimum Detectable Effect) refers to the smallest difference between the control and the variant that the test can reliably detect. It's a choice, not a measured value: you decide what level of improvement is worth detecting.
This choice has a dramatic effect on the required sample size. Detecting a small effect (for example, increasing a conversion rate from 5% to 5.2%, a relative improvement of 4%) requires significantly more traffic than detecting a large effect (increasing the same rate from 5% to 6.5%, a relative improvement of 30%). In practice, this means that a minor change—a button color, a word in a title—requires a considerably larger sample size than a complete page redesign, with the same level of traffic, simply because a more modest effect is expected.
The practical consequence is simple: on a site with moderate traffic, it is better to concentrate the first tests on changes from which a clear effect is expected (restructuring of a page, simplification of a journey) rather than on micro-adjustments which would take months to produce a usable result.
The level of confidence and statistical power
Two other, more technical parameters complete the calculation. The confidence level (often set at 95%) indicates the probability of incorrectly declaring a test the winner when there is actually no difference between the two versions—what is called a false positive. The statistical power (often set at 80%) indicates the probability of detecting a real effect if one exists, rather than incorrectly concluding that there is no difference—a false negative.
These two values (95% and 80%) are conventions widely used in the A/B testing industry, not absolute rules. Increasing them (for example, aiming for 99% confidence) reduces the risk of an incorrect conclusion but further increases the required sample size; reducing them speeds up obtaining a result, at the cost of a higher risk of drawing an incorrect conclusion. For a test with limited consequences (an easily reversible adjustment), more flexible thresholds may be justified; for a test whose result will determine a costly decision to implement, stricter thresholds are preferable.
How to estimate your sample size in practice
In practice, it's rarely necessary to calculate the underlying statistical formula yourself. Most A/B testing platforms, including BlastOptimize, include a calculator that simply asks for the current conversion rate and the minimum effect you want to be able to detect, and directly returns the required sample size per variant, as well as an estimate of the test duration based on the current page traffic.
This estimate must be made before launching the test, never after. It serves to decide whether the test is feasible within a reasonable timeframe given the available traffic, and if not, to adjust either the scope of the change being tested (aiming for a broader effect, therefore a higher MDE), or the scope of the test (grouping several low-traffic pages rather than testing an isolated page), or to consider other research methods (qualitative user testing, surveys) when the traffic simply does not allow for reaching a sufficient sample within a reasonable timeframe.
The "peeking" mistake: looking at the result before the end
Once the sample size is estimated, the most important discipline is to wait until it is reached before drawing a conclusion—even if the dashboard shows an impressive discrepancy after only a few days. This behavior, known as "peeking," is one of the most frequent causes of false results in A/B testing: the statistical significance indicators displayed in real time by most tools are calculated continuously, and a discrepancy may appear significant at a given moment and then decrease, or even reverse, once the full sample size is reached.
The simplest practical rule to avoid this pitfall is to set, before launching the test, both a minimum sample size and a minimum duration (generally at least one to two weeks, to cover the variations between weekdays and weekends), and to consider the result as definitive only when both conditions are met simultaneously.
What to do when traffic is too low for a standard test
Not all websites have the traffic necessary to test micro-optimizations with a comfortable sample size over a few days. When traffic is limited, several adjustments can help continue to improve:
- Testing changes with a high expected impact rather than micro-adjustments, to reduce the required sample size.
- Group the metrics by following a goal higher in the funnel (e.g. click to cart rather than final purchase), when it remains relevant to the hypothesis being tested, since more frequent events require a smaller sample.
- Extend the duration of the test beyond the usual two weeks, by accepting a longer delay before the decision.
- Supplement A/B testing with qualitative methods (user tests, session recordings, customer interviews) which do not require a large volume of traffic to produce actionable insights.
A concrete example to visualize the reasoning
To make these concepts more concrete, let's take a purely illustrative example. Imagine a landing page with a current conversion rate of 3%, and a team that wants to detect a minimum relative effect of 15% (i.e., a change from 3% to approximately 3.45%), using the usual thresholds of 95% confidence and 80% statistical power. A sample size calculator would indicate, in this scenario, that several thousand visitors per variation are needed for the test to be reliable—the exact order of magnitude depends on the formula used, but the principle remains the same: the smaller the desired effect is relative to the initial rate, the faster the required sample size grows.
If the same page receives only a few hundred visitors per week, this test would take several months to reach the required sample size—a timeframe rarely compatible with the pace of a marketing team. Two options then present themselves: either revise the hypothesis to aim for a broader effect (a more structural change rather than a minor adjustment), or accept a higher MDE, which reduces the test's sensitivity but also its duration. This type of trade-off, made consciously before launch, is better than a test launched without careful consideration and prematurely interrupted due to impatience.
Frequently Asked Questions
Should the same sample be used for the control and the variant?
In the vast majority of cases, yes: an equal sharing of traffic between the two versions is the most efficient configuration to achieve statistical significance as quickly as possible, with equal total traffic.
Can we test more than two variants at a time?
Yes, but each additional variant dilutes the available traffic per branch and increases the time required to obtain a sufficient sample size for each. An A/B/C/D test, with the same total traffic, requires significantly more time than a traditional A/B test to reach a reliable conclusion on each variant.
Can a test be reliable with a small website?
Yes, provided that expectations are adjusted: prioritize changes with high potential impact, accept longer test durations, and do not hesitate to supplement A/B tests with methods that do not depend on traffic volume, such as qualitative user testing.
Key takeaways
Sample size isn't a technical detail reserved for statisticians; it's the parameter that determines whether an A/B test will produce a reliable conclusion or a misleading result. It depends on the initial conversion rate, the magnitude of the effect you're trying to detect, and the required level of confidence—three elements that are better estimated before launching a test than discovered, after the fact, that they invalidate the conclusion. The good news is that a sample size calculator integrated into the testing tool is sufficient, in the vast majority of cases, to perform this calculation for the marketing team.
BlastOptimize integrates this calculator directly into its dashboard, providing an estimate of the required test duration based on the actual traffic to the tested page, to prevent running a test that's bound to be inconclusive. If you're unsure about the sample size needed for your next test, this is a good starting point to decide before even creating your variant.



Comments are closed.